


Bounding Box Annotation: 5 Mistakes That Hurt Model Accuracy
The five most common bounding box errors that hurt model performance, and how to prevent each one with IoU checks and QA.
Precise BPO Solution is an India-based data labeling and annotation company with a 540+ strong in-house team across all our service domains. We deliver human‑verified training data for AI and ML teams across image, video and text, with 330M+ video frames labeled since 2017.
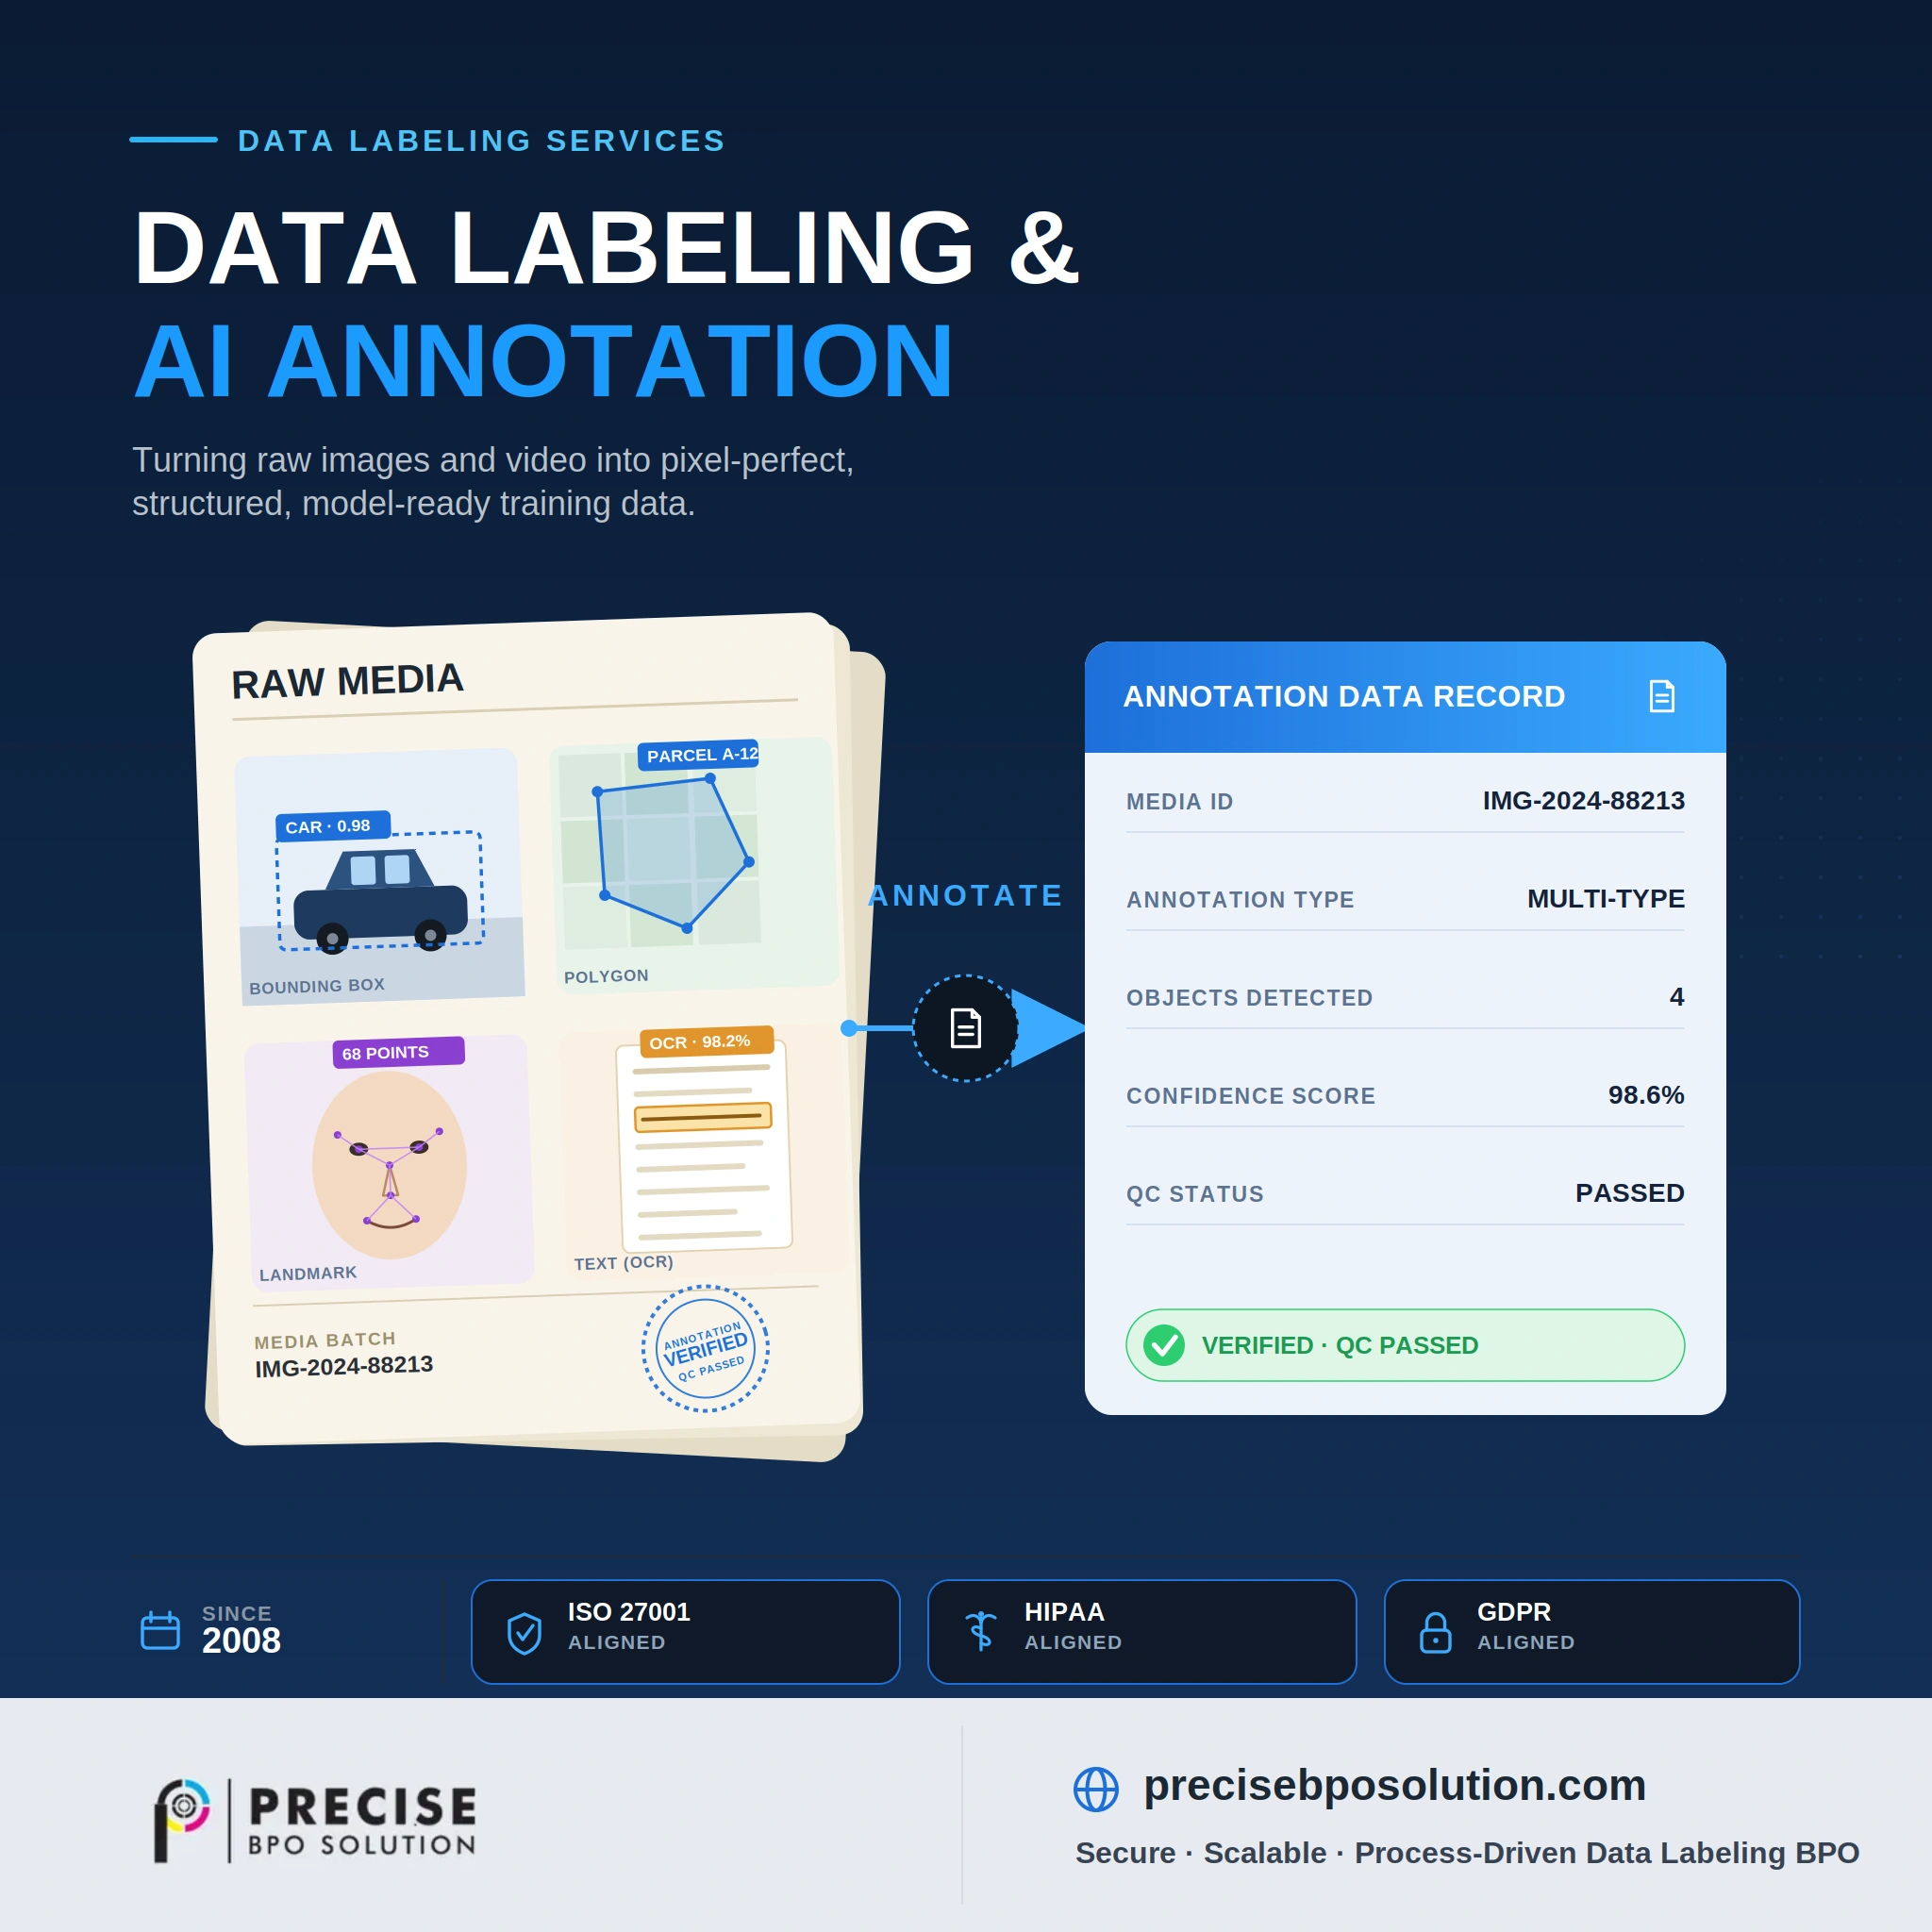
Illustrative examples of each annotation type we deliver, so you can see what to expect.
Precise BPO has been in business since 2008 and has labeled training data for AI teams since 2017. Today we work with teams building computer vision, autonomous driving, medical imaging, NLP and LiDAR systems, all from our delivery center in Pune. Our round-the-clock shifts overlap working hours in the US, UK, EU and APAC. We build every dataset to your model specification, label schema and quality threshold.
Our annotators work across bounding boxes, polygons, semantic masks, keypoint landmarks, 3D cuboids and NLP tagging, including NER, intent and RLHF preference data for fine-tuning large language models. We can work in your annotation platform or ours.
For high-volume computer vision work, you can go from pilot to production with us without building a labeling operation of your own. Every batch arrives ready to load into your training pipeline.
Data annotation, also called data labeling, is the process of adding structured metadata to raw data (images, video frames, text, audio or point clouds) so that machine learning models can recognize and classify it accurately. Annotators apply bounding boxes, polygons, semantic masks, keypoints, text tags and attribute labels to raw datasets, giving the model correct examples to learn from. Reliable labels come from annotators trained on your taxonomy, which is why many AI teams hand this work to specialists instead of pulling engineers into manual tagging.
Bounding box labels drive object detection, pixel masks drive segmentation and keypoints drive pose estimation. NLP models depend on text annotation in the same way. Good labels also depend on domain knowledge: how edge cases are handled, how classes are defined and what schema your model expects.
We annotate data for autonomous vehicles, healthcare, agriculture, retail, geospatial, language AI, document AI and manufacturing, and we work from each industry's own label taxonomy.
We label camera, LiDAR and radar data for self-driving perception teams, from 2D boxes to 3D cuboids, at production volume.
We annotate radiology scans, pathology slides and surgical video under HIPAA-aligned workflows, tracing organs, tumors and anatomical landmarks for diagnostic and surgical-robotics models.
We label satellite and drone imagery for crop detection, disease classification and yield estimation.
We tag product and catalog images for visual search, recommendation engines and inventory systems, including fashion and apparel attributes.
We annotate satellite and aerial imagery: building footprints, road networks and land-use change for urban planning and environmental monitoring.
We label text for LLM fine-tuning and conversational AI, including NER, intent classification, sentiment and RLHF preference data in 20+ languages.
We label invoices, KYC documents and handwritten forms for OCR and fraud-detection pipelines, under the strict data controls financial clients require.
We label production-line images for defect detection and component classification, supporting predictive maintenance and visual inspection.
Most teams run into the same problems when they scale labeled datasets. These are the ones we're usually brought in to fix.
Crowdsourced or freelance work looks cheap until your model's mAP drops and engineers end up re-labeling everything. In our standard process, someone other than the annotator reviews every batch before it reaches you. See how our QA works →
In-house teams hit capacity ceilings fast. Recruiting, onboarding and training annotators typically take 4–6 weeks before a single label is created. Your pilot can start within 48 hours of signing the NDA. See our annotation process →
Medical, financial and other regulated projects often require data to stay in controlled environments, which rules out freelancers and crowd workers. Everyone on our team is a permanent, NDA-signed, background-verified employee. Data moves over encrypted SFTP, with role-based access, VPN tunnels and full audit logs. We can also handle HIPAA-aligned de-identification before labeling starts.
Our dedicated teams run $4–$8/hr, with QA, tooling and project management included, which is 40–60% below US/UK rates. See pricing →
Labeling guidelines drift when a team grows and nobody owns the rules. We assign dedicated project managers who maintain guideline consistency across every specialist, batch and sprint.
Models trained on clean data fail on real-world noise, occlusion and rare classes. Our medical, automotive and agricultural specialists know where edge cases tend to appear and label them from the start, something generalist vendors often miss.
Not sure yet? We'll label your first 100 images at no cost.
✓ No commitment ✓ NDA signed first ✓ 100 images delivered in 24–48 hours
Start a free pilot →We deliver labeled datasets in your required format, from bounding boxes to LiDAR and NLP.
Rectangular boxes around objects for detection and classification.
Bounding box annotation →Pixel-level class masks for autonomous vehicles, medical images and satellite imagery, at 99.2%+ accuracy.
Semantic segmentation →Precise outlines for irregular objects such as crops, vehicles, body parts and architectural elements.
Polygon annotation →Lane detection, road markings, cable routing and other linear infrastructure for autonomous systems.
Polyline annotation →Keypoints for pose estimation, facial recognition and human action recognition.
Landmark annotation →3D point cloud labeling for robotics, autonomous vehicles and industrial automation.
3D cuboid & LiDAR annotation →NER, intent classification, sentiment tagging, span labeling and RLHF preference data for LLM training and fine-tuning.
Text annotation →Frame-by-frame multi-object tracking, action recognition, temporal event labeling and behavior analysis for surveillance, sports, autonomous driving and media AI. Supports per-frame exports and interpolated tracks.
Ask about video annotation →PHI and PII redaction for medical records, financial documents and legal filings.
De-identification →Lesion detection, organ segmentation and radiology AI datasets, labeled in HIPAA-aligned workflows.
Medical annotation →Object detection, LiDAR, lane detection and 3D cuboids for ADAS and self-driving perception stacks.
Autonomous vehicle annotation →Crop monitoring, disease detection and drone imagery labeling for precision farming models.
Agriculture annotation →Garment tagging, attribute labeling and visual-search datasets for fashion AI and e-commerce recommendation engines.
Fashion annotation →Player tracking, ball detection, skeletal keypoints and event labeling for sports analytics, coaching tools and broadcast AI.
Sports annotation →Content classification and tagging for moderation pipelines, built for platforms and trust & safety teams.
Explicit content annotation →We work inside the platform your team already uses, including CVAT, Labelbox, Roboflow, SuperAnnotate and V7, and deliver in the format your ML pipeline requires.
The annotation type you pick affects both model performance and labeling cost. This table compares the main types on shape, speed, cost and precision. If bounding boxes are your main format, our bounding box annotation guide covers the common mistakes and how to avoid them.
| Criteria | Bounding Box | Polygon / Instance | Semantic Segmentation | Keypoint / Landmark |
|---|---|---|---|---|
| Shape | Rectangle: axis-aligned or rotated | Vertex-traced outline per object instance | Pixel-level mask per class | Coordinate points on joints or landmarks |
| Best for | Bounded objects: vehicles, people, products | Complex shapes: irregular or overlapping objects | Scene understanding: drivable area, background separation | Pose estimation, facial analysis, AR/VR datasets |
| Annotation Speed | Fastest: single drag per object | Moderate: vertex-by-vertex | Slowest: pixel-by-pixel fill | Fast: point placement per joint |
| Cost Efficiency | Highest: minimal effort per object | Medium: scales with shape complexity | Lowest: most effort per image | High: fast but requires domain expertise |
| Boundary Precision | Object-level (includes background) | High: shape-accurate | Pixel-level | Point-exact per joint |
| Video / Temporal | Excellent: fast frame-by-frame tracking | Good: higher effort per frame | Poor: very high effort per frame | Excellent for pose tracking across frames |
| Common Use Cases | Retail, ADAS, medical, surveillance, drone imagery | Autonomous driving, agriculture, satellite, fashion | Autonomous vehicles, medical imaging, aerial mapping | Human activity recognition, sports analytics, AR/VR |
| Our service page | Bounding Box | Polygon | Segmentation | Landmark |
Not sure which annotation type fits your project? Talk to one of our annotation specialists and we'll recommend an approach based on your data, model architecture and accuracy targets. For lane markings and other linear features, see polyline annotation, which isn't covered in this table.
Here is how a project moves from requirements review to final delivery.
We define annotation goals, object classes, labeling taxonomy, quality thresholds and output schemas with your ML team before any labeling begins, so every annotator works to a single, locked specification.
We receive raw images, video, LiDAR or text files over encrypted SFTP, normalize them to standard formats and organize them into batches on secure infrastructure that only NDA-bound staff can reach.
Our in-house annotators label your data in the tool you specify or on our own platform, using bounding boxes, polygons, segmentation masks, keypoints, LiDAR cuboids or text labels as the project requires. Dedicated domain specialists handle medical, automotive, agricultural and NLP datasets.
Every standard batch passes annotator self-review, an independent blind review with IoU and agreement metrics, and senior sign-off. On bounding box work we target an error rate under 0.2%.
You review each annotated batch and send feedback, and we work through it in structured revision cycles. We update the guidelines and lock them before the next batch begins, which keeps labels consistent across the full dataset.
We deliver outputs in your required format through secure transfer, within agreed SLAs. We also support active learning pipelines, model retraining cycles and extended annotation programs.
What changed for clients after they moved annotation to us. Names withheld under NDA.
We labeled vehicles, pedestrians and other road users with pixel-level masks, following the client's class definitions. Annotation for autonomous driving →
The client's search relevance had plateaued on a catalog of 500K+ products with inconsistent, partly manual tagging. We rebuilt the attribute set from scratch and tagged the full catalog under a locked taxonomy. Retail catalog annotation →
Polygon and pixel-level tagging, reviewed by QA specialists. Medical imaging annotation →
Dense defect segmentation on production line images to train automated inspection AI. Semantic segmentation for defect detection →
A German AgriTech team needed multi-class boundaries fine enough to separate young crops from weeds in dense drone imagery, a task their previous vendor's polygons couldn't hold consistently. Crop and drone imagery annotation →
3D cuboids and keypoints labeled for precise grasp points across varied object types and orientations. 3D cuboid annotation for robotics →
A 5–7 day manual claims review was the client's biggest bottleneck. Instance segmentation of exterior vehicle damage let their model flag and route claims automatically, with adjusters reviewing only the edge cases. Segmentation for claims automation →
Every labeling type has its own quality benchmark, tracked project by project. We publish these figures so you can check them against your own acceptance criteria.
On every project, our 3-tier QA targets inter-annotator agreement of 0.92 or higher (Cohen's kappa).
First-pass labeling with embedded rule checks. Self-review against the guideline checklist before handoff.
A separate specialist reviews blind, runs IoU and pixel-diff checks, and measures inter-annotator agreement per batch.
A random 10% of every batch is re-reviewed by a senior specialist, and any drift is flagged before delivery.
If you're comparing vendors, our Data Annotation Quality Standards guide covers what to ask about consistency and validation before you commit.
570+ Clients Trust Us With Their Training Data
Across 27+ countries
Client names withheld under NDA. Case studies and references available on request.
Three ways to build AI training data, compared on the points that decide timelines and cost. This is a general comparison; check any vendor's SLA before you decide.
| Criteria | In-House Team | Generic BPO | Precise BPO |
|---|---|---|---|
| Time to first label | 4–6 weeks | 1–2 weeks | Pilot starts within 48 hours of NDA; delivered in 24–48 hours |
| Cost vs. in-house | Baseline (highest) | Lower, but markups apply | 40–60% below US/UK rates |
| AI domain expertise | Depends on hiring | Often generalist | In-house, domain-trained annotators |
| QA process | Depends on team maturity | Often one review pass | 3-tier QA, target of up to 99.8% |
| Scale-up speed | Months (hiring cycles) | Days–weeks | Days |
| Security alignment | Depends on your own controls | Confirm in the SLA | ISO 27001-, HIPAA- & GDPR-aligned |
| Freelancer risk | None (in-house) | Ask about subcontractors | No freelancers |
| Free pilot | N/A | Sometimes offered | 100 images free |
| Dedicated PM | Internal only | Shared resource | Dedicated from Day 1 |
Want to see how it works on your data? Start with a free 100-image pilot.
Start a free pilotFeedback from AI teams that moved their annotation work to us.
Their object detection labels came out above our internal benchmarks. They picked up our class hierarchy quickly, and in review they flagged edge cases our own team had missed. We started with a 10K-image batch and we're now past 2M frames, with quality holding steady.
We didn't want a vendor that only claimed compliance. Precise BPO gave us documentation and signed a BAA, and their annotators understood the clinical context of what they were labeling. Within three months of retraining, our model's recall was up 18%.
We'd already tried two crowdsourcing platforms, and the results were inconsistent from batch to batch. Precise BPO's polygon annotations for our crop segmentation model stayed consistent across 3M+ images, and our project manager was available across time zones.
Every annotator works from a locked taxonomy before labeling begins, and every batch goes through the same 3-tier QA unless you ask for a lighter review. That consistency is what lets clients scale from a pilot to millions of images while holding label quality.
Start a free pilotWe started with data entry and document processing and have labeled AI training data since 2017, now covering bounding boxes, polygons, LiDAR point clouds and text datasets.
Dedicated, background-verified, NDA-signed staff across all our service domains, with trained annotators on every labeling project. No freelancers or crowdsourced workers.
NDA-bound staff, encrypted transfer and audit logs, with a BAA available for HIPAA-scoped medical imaging projects.
Each standard batch ends with a senior sampling audit.
Our costs are 40–60% below US/UK rates because you don't carry recruitment or tooling overhead.
We label in the platform you already use and deliver in the format your pipeline loads.

Per-item and hourly rates with no hidden fees. Volume discounts start at 50K items.
| Annotation Type | Rate Range (USD) | Best For |
|---|---|---|
| Bounding Box | $0.01 – $0.06 | Object detection and tracking |
| Polygon / Instance | $0.08 – $0.35 | Precise shape outlines, irregular objects |
| 3D Cuboid / LiDAR | $0.12 – $0.50 | Robotics, autonomous vehicle depth data |
| Segmentation | $0.10 – $0.45 | Autonomous driving, medical imaging |
| Polyline | $0.06 – $0.25 | Lane detection, road markings |
| Landmark & Keypoint | $0.015 – $0.05 | Pose estimation, facial recognition |
| De-identification | $0.015 – $0.05 | Medical records, PHI redaction |
| Text & NLP | Quoted per project, or hourly at $4–$8/hr | NER, intent, RLHF preference data |
| Video Tracking | Quoted per project, or hourly at $4–$8/hr | Multi-object tracking, action labeling |
| Team Type | Rate Range | Best For |
|---|---|---|
| Annotation Specialist | $4 – $6 / hr | High-volume standard annotation |
| Senior / Domain Specialist | $6 – $8 / hr | Medical, LiDAR, complex segmentation |
| QA Reviewer | $5 – $7 / hr | Independent validation and auditing |
The hourly model suits dedicated team engagements, ongoing programs, or mixed annotation types. Minimum 160 hrs/month. NDA, IP rights and SLA included.
We've worked with 570+ clients across 27+ countries. Startups running a first pilot and larger teams replacing an existing vendor get the same process: a free pilot batch, our standard 3-tier QA, and an in-house team with no freelancers.
Our Pune delivery center runs round-the-clock shifts, so someone is working during your hours, wherever your team is based.
Answers on scope, accuracy, formats, security and pricing: the questions we get asked most.
Data annotation is the work of labeling raw data (images, video, audio, text or 3D point clouds) so a model knows what it is looking at. The labels tell it which objects, patterns or meanings are present. See our complete guide to data labeling for a deeper overview.
We handle image and video annotation (bounding boxes, polygons, semantic and instance segmentation, keypoints, object tracking). We also do 3D LiDAR point cloud labeling, text annotation (classification, named entity recognition, sentiment tagging) and audio transcription for computer vision, NLP and speech AI projects, all under one engagement. If your source material is scanned documents or paper records, our data entry and data conversion teams can digitize it before labeling starts.
Every standard batch goes through three tiers. In Tier 1, annotators label from client-approved guidelines and self-review against a checklist. In Tier 2, an independent QA specialist does a blind review and measures IoU and inter-annotator agreement. In Tier 3, a senior specialist signs off and re-reviews a 10% sample of the batch. For bounding box work we target an error rate under 0.2%; the other annotation types score 98.9–99.4% on our benchmarks above.
Each project starts with an ontology and annotation schema built around your model's classes. From there you can add volume, send new data for active-learning cycles, or come back after retraining your model. Each addition runs as a new batch against the same locked class definitions, with agreement tracked per batch.
We label data for autonomous vehicles (LiDAR, camera fusion), healthcare AI (medical imaging, radiology), retail and e-commerce (product detection, shelf analytics), agriculture (crop and disease detection), satellite and geospatial imagery, financial document AI, manufacturing, robotics, surveillance and security, sports analytics and NLP products.
We keep labels consistent with written annotation guidelines, a documented class taxonomy, inter-annotator agreement scoring and gold-standard calibration sets. Before any production batch begins, annotators complete calibration tasks scored against gold data to verify their understanding of edge cases and class boundaries. QA reviewers flag annotation drift, class ambiguity and boundary inconsistencies during review. See our annotation governance framework for full details.
We deliver in the format your ML pipeline requires: COCO JSON, Pascal VOC XML, YOLO TXT, LabelMe JSON, CSV and custom schemas. For video, we deliver MOT-format tracking files or frame-by-frame JSON. For NLP, outputs include CoNLL for NER, JSON for classification, and custom formats for intent/slot labeling. These formats work with standard PyTorch and TensorFlow data loaders, Roboflow and major cloud ML services.
Pricing depends on dataset volume, the complexity of the annotation type, class density per image or document, QA depth and turnaround requirements. Common engagement models include per-image, per-object, per-frame, hourly and monthly retainer. All engagements include a free pilot batch before you commit. See our data labeling pricing guide or request a tailored quote.
Our workflows are aligned with ISO 27001, HIPAA and GDPR requirements, and we can share security documentation and sign a BAA for HIPAA-scoped projects. Every annotator signs an NDA before project access is granted. Access is permission-scoped, so annotators only see the dataset segments assigned to them. Data moves only over encrypted channels such as SFTP and VPN, so your training data and model IP stay protected.
No in-house team required. You send raw images, video or text and receive labeled datasets back. We run the full engagement with our own NDA-bound annotators. Comparing providers first? Our guide to the top data annotation companies shows how the main vendors differ.
Our annotation capabilities across computer vision, NLP, video and audio, in one PDF.
Practical guides on data labeling, annotation pricing and choosing a vendor, written for AI and ML teams. We also publish data entry guides for teams working from paper or scanned records.
Your pilot starts within 48 hours after the NDA is signed, and the batch is delivered within 24–48 hours, reviewed by our QA team, at no cost and with no commitment.