How to Evaluate Online Data Entry Outsourcing Vendors (2026)
A framework for evaluating online data entry outsourcing vendors — what to ask about accuracy, security, pricing, and scalability before you sign.
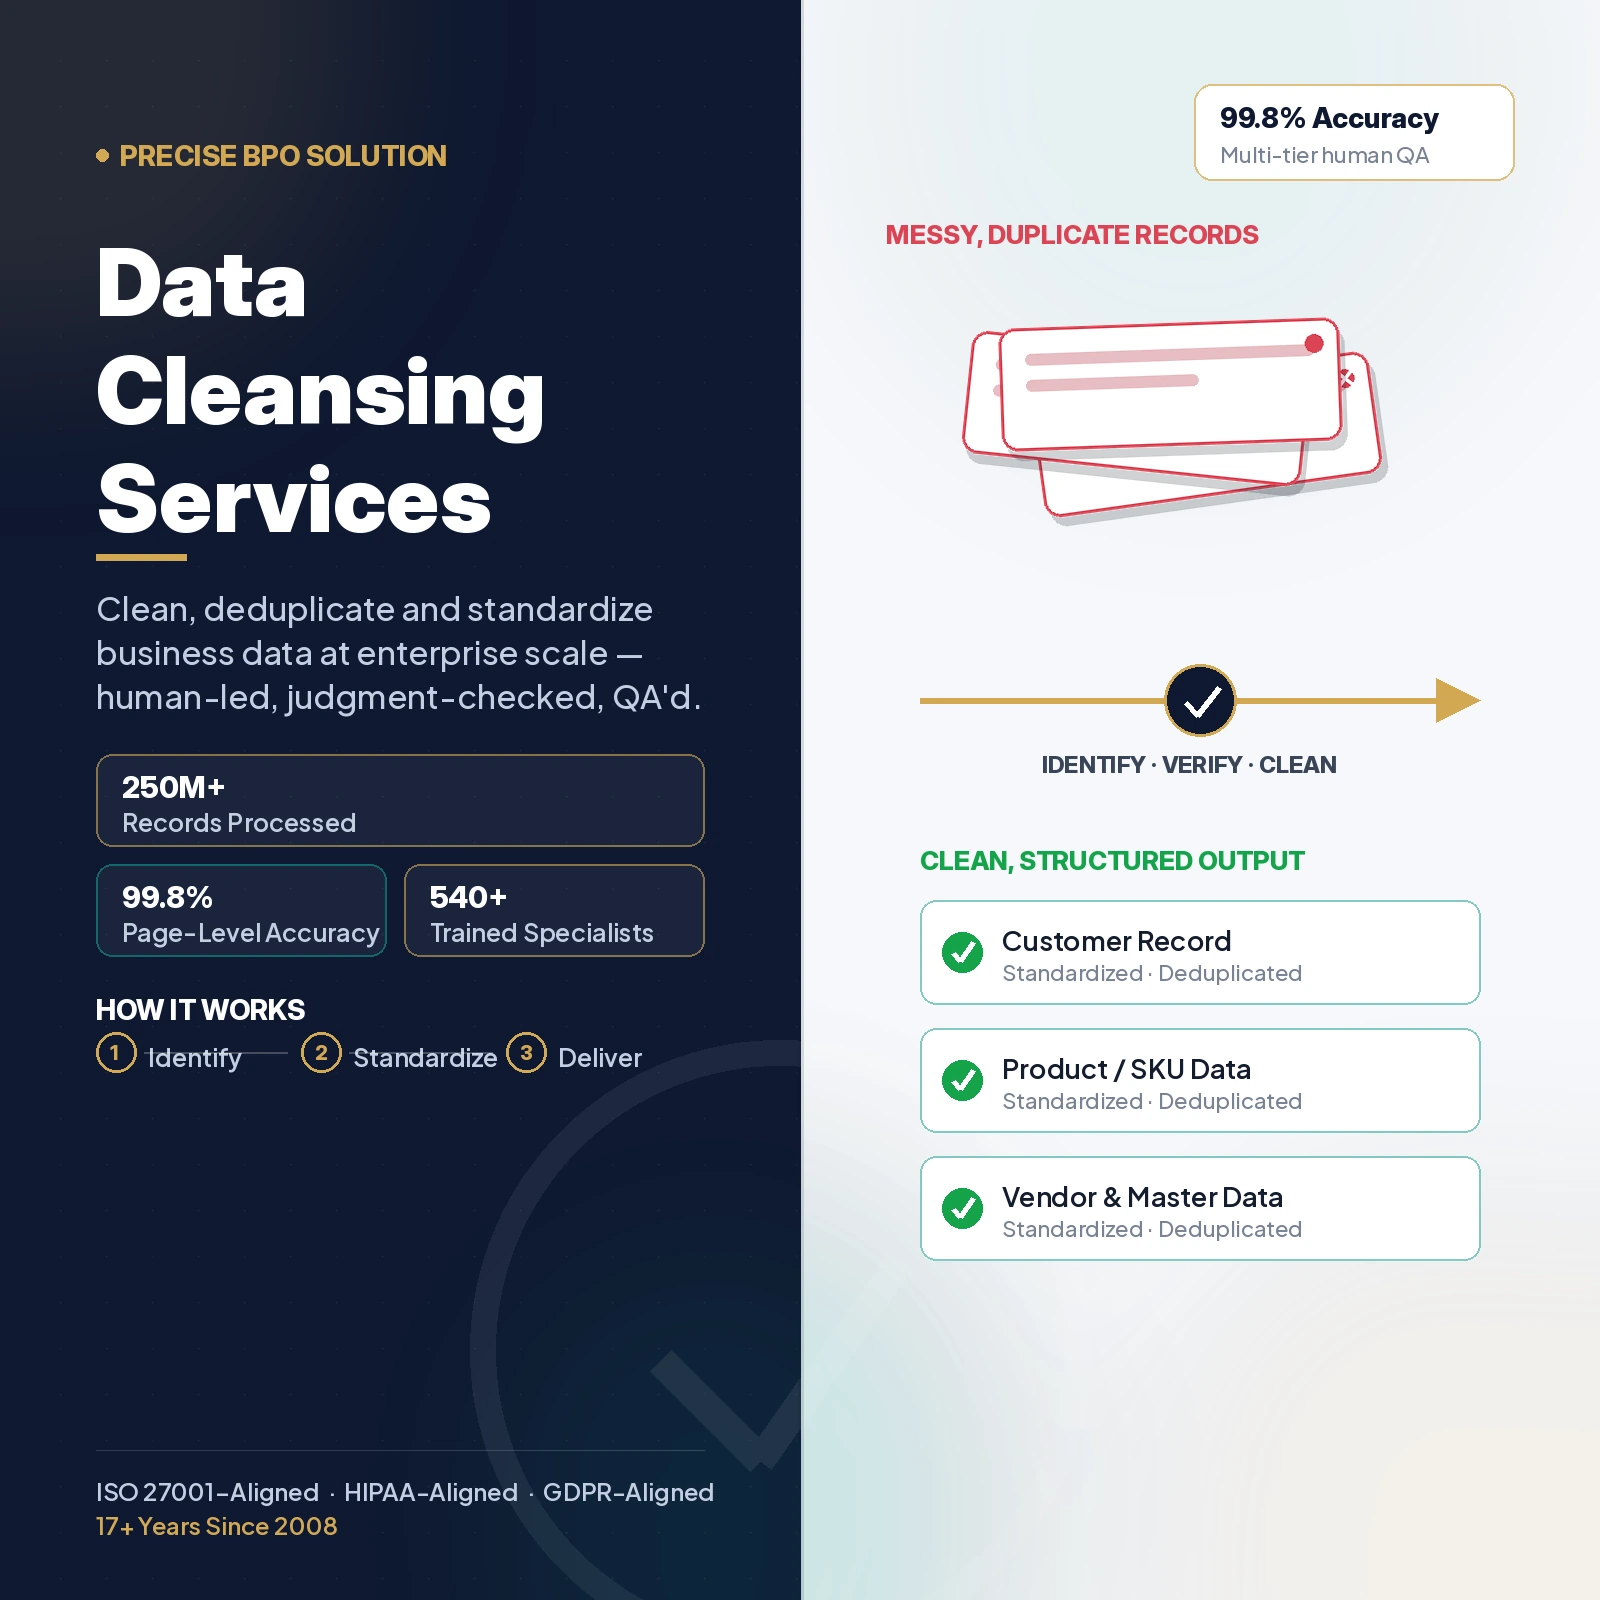
We provide outsourced data cleansing services for large business datasets. Our team cleans, deduplicates, standardizes and validates records, and anything that needs a judgment call is reviewed by a trained specialist, not deleted by a script. Our 540+ In-House Team in Pune, India has cleansed 250M+ records since 2008, working to ISO 27001-aligned controls, with GDPR- and HIPAA-aligned handling where it applies.
Security & Compliance
Serving enterprises across US · UK · Canada · Australia · Europe · Middle East · APAC · LATAM
Most businesses have plenty of data. The trouble is that it holds duplicate records, outdated information, incomplete fields and mismatched formats across customers, products and addresses. Precise BPO Solution reviews that existing data and corrects, standardizes or resolves those problems before it is used for reporting, CRM, ecommerce or migration. Our data cleansing services combine fixed matching rules with a specialist's review.
Since 2008, our 540+ In-House Team has processed 250M+ cleansing records, part of 990M+ records across all Precise BPO services. Our controls are aligned to ISO 27001, HIPAA and GDPR (more about how we work), and we work with clients in more than 27 countries.
Our work covers customer and CRM database cleanup, duplicate record review, product and ecommerce catalog cleansing, master data and legacy database cleanup, and standardization and validation. Cleansing is different from our online data entry services, which capture new records rather than clean existing ones. If your data is still on paper or in scanned files, our data conversion service can digitize it first. If it is headed for an AI or analytics pipeline, our data labeling services pick up where cleansing leaves off.
Captures, creates, updates or transfers information into a system.
Reviews existing information to identify duplicates, inconsistencies, incomplete fields, formatting issues and other quality problems.
We clean customer, product and supplier data across eight industries, from automotive and ecommerce to healthcare, financial services, logistics, real estate, market research and manufacturing.
Dealer, parts and vehicle-owner databases accumulate duplicate contacts and inconsistent VIN or part-number formatting over time — we clean and standardize these records so service, sales and parts teams work from one consistent dataset. Related maintenance records are also supported through our vehicle data entry services.
Product catalogs, SKU lists and customer records grow duplicate entries and inconsistent attributes as sellers add channels — our catalog cleansing and customer deduplication keep listings and CRM data accurate at scale.
Patient and provider records are cleaned and standardized under HIPAA-aligned confidentiality workflows, reducing duplicate patient entries while preserving legitimate distinct records. If claims data needs entering too, our medical claims data entry service covers it.
Customer, policyholder and account records are deduplicated and standardized to support accurate reporting and compliance. Firms already digitizing statements and invoices also use our financial data entry services alongside cleansing.
Shipper, carrier and address databases are standardized and deduplicated to reduce failed deliveries and reconcile records across warehouse and freight systems.
Property, buyer and lender records are standardized and duplicate listings resolved. Work specific to loan files goes through our mortgage data entry services.
Survey and respondent databases are deduplicated and standardized to remove duplicate panelists and inconsistent responses before analysis. If you also need survey forms keyed in, see our market research data services.
Supplier, vendor and client master data records are standardized and deduplicated to support accurate procurement, billing and reporting across departments and locations.

Our team cleans customer, product and business databases using matching rules agreed with you, specialist review of anything ambiguous, and a final QA pass.
We remove duplicate customers, standardize addresses and contact fields, and review inconsistent records, so your CRM and sales systems work from one reliable source.
We identify, compare and verify duplicate records, then merge, keep separate or escalate each group according to your business rules.
We clean up SKUs, find duplicate listings, standardize product names and attributes, review pricing data and keep categories consistent. If you also need new products entered, our product data entry service works to the same rules.
We clean legacy and master databases, standardize and normalize fields, and review incomplete records, usually ahead of a migration or system upgrade.
Names, addresses, phone numbers, dates, product attributes and codes are brought into one consistent format across your records.
We validate records against your rules, verify exceptions manually, and run multi-level QA, including maker-checker review where it applies, before anything is delivered.
Duplicate customer data is rarely a simple exact-match exercise. Large CRM and customer databases accumulate records that look similar but describe different people, households or business entities — and records that look distinct but are, in fact, the same customer under an old address or a new email. Deleting on appearance alone risks removing legitimate data, so every engagement follows the same human-led sequence: Identify → Compare → Verify → Decide → QA.
Family members, housemates or spouses on a joint account can share an address, a surname and purchase history without being the same customer.
Branches, franchise locations or departments of the same business frequently share a phone number, address, or point of contact while remaining separate accounts.
Businesses with similar, abbreviated or misspelled names can appear duplicated when they are separate legal entities or unrelated companies.
A shared landline, office number or mailing address is a signal to investigate — not proof on its own that two records describe the same customer.
Customers with old and new contact details or several email addresses, and accounts carried over from a prior system, need context before any merge decision.
Missing fields, partial names or inconsistent formatting can make two genuinely different customers look like a match — or hide a real duplicate.
Confirmed duplicates are merged according to your business rules, preserving the most complete and accurate field values.
Records that share details but describe distinct people or entities are kept as separate, legitimate records.
Ambiguous groups are flagged with supporting evidence and sent to your team for sign-off instead of being decided without you.
Migrating dirty data into a new CRM, ERP or database only moves the problem — duplicate customer records, inconsistent fields and incomplete data surface again on the other side. Cleaning the data before the migration catches these issues while they are still easy to fix.
| Step | What Happens | Why It Matters Before Migration |
|---|---|---|
| 1. Profile | Review the source dataset's structure, field completeness and overall quality. | Surfaces the scale and type of issues before a migration date is set. |
| 2. Identify Duplicates | Run duplicate detection across customer, product or master records. | Prevents duplicate records from being copied straight into the new system. |
| 3. Standardize | Normalize names, addresses, dates, codes and reference values into one format. | Matches the field formats the new CRM, ERP or database expects. |
| 4. Validate | Check required fields, formats and business rules against the target system's requirements. | Reduces failed imports and post-migration error queues. |
| 5. Map / Prepare Fields | Align source fields to the destination system's field structure and naming. | Avoids manual remapping and rework after go-live. |
| 6. Review Exceptions | Escalate ambiguous duplicates and incomplete records for your team's sign-off. | Keeps legitimate records from being dropped or merged incorrectly. |
| 7. Prepare Final Import Dataset | Deliver the cleansed, mapped dataset in your required structured format. | A clean, migration-ready dataset your technical team can import directly. |
We prepare structured output formatted for your existing systems and workflows. Your technical team runs the import; we don't connect directly to your CRM or ERP.
From customer records to product catalogs, we clean the datasets your teams rely on every day.
| Data Type | Common Issues | Cleansing Focus |
|---|---|---|
| Customer & CRM records | Duplicates, missing fields | Dedup, standardization |
| Product & SKU / catalog data | Duplicate SKUs, naming | Attribute standardization |
| Supplier & vendor data | Inconsistent naming | Master data cleanup |
| Business & master databases | Legacy inconsistencies | Field normalization |
| Address & contact databases | Format inconsistencies | Address standardization |
| Financial & insurance records | Duplicate accounts/policies | Verification, dedup |
| Healthcare records | Duplicate patient entries | Confidential handling |
| Spreadsheet & CSV/Excel datasets | Mixed formats, junk rows | Structuring, cleanup |
| Legacy & structured business datasets | Migration-blocking issues | Pre-migration cleansing |
From secure intake to final delivery, with specialist review and multi-level QA in between.
We receive the dataset and your instructions through encrypted channels, and confirm field structure, scope and matching preferences before touching a record.
Specialists identify duplicates, missing fields, inconsistent formats and quality issues across the dataset before deciding how each type of issue should be handled.
We agree and document the matching and validation rules with you: what counts as a duplicate, what gets standardized, and what must always be escalated.
Human specialists review records that need judgment: apparent duplicates, incomplete entries and conflicting values.
Confirmed issues are corrected, and names, addresses, contact fields, product attributes and reference values are normalized into one consistent format.
Uncertain or ambiguous records — where deletion or merging could remove legitimate data — are escalated to your team according to agreed rules instead of being decided without you.
Processed records are reviewed against defined quality standards through completeness checks, discrepancy flagging and supervisor review before release.
The cleansed dataset is delivered in your agreed structure (CSV, XLSX, XML or JSON), with a QC log per batch and a dedicated account manager for post-delivery support.
We deliver cleaned data formatted for import into the CRM, database or catalog platform your team already uses, so there is no reformatting or re-entry on your side.
Six example projects from clients in the US, UK, Canada, Australia, the UAE, Singapore and Europe, covering CRM deduplication, catalog cleansing, migration preparation and legacy data cleanup.
A side-by-side look at cleansing data in-house, with a general BPO, or with Precise BPO.
| Criteria | In-House Team | Generic BPO | Precise BPO |
|---|---|---|---|
| Record-Level Accuracy | Varies with training and QA | Varies by provider and QA process | ✓99.8% — rules-based + multi-level QA |
| Setup Time | Weeks of hiring and training | Varies by provider | ✓Project start within 24–48 hours |
| Scalability for Large Cleanup Projects | ✕Difficult — fixed headcount | !Limited — slow ramp-up | ✓Scales up with our 540+ In-House Team |
| Cost vs. In-House | Baseline (salary + infra + benefits) | Some savings; varies by provider | ✓40–60% Below US/UK Rates |
| Security & Compliance | ✕Depends on internal policies | !Varies by provider | ✓Aligned to ISO 27001, HIPAA and GDPR |
| NDA & Confidentiality | !Internal policies only | !Standard contract clauses | ✓NDA signed on every engagement |
| Duplicate Decisioning | !Ad hoc, inconsistent rules | !Review depth varies by provider | ✓Merge / keep separate / escalate — human-reviewed |
| Dedicated Data Specialists | ✓But costly to retain | ✕Often general-purpose teams | ✓Trained cleansing team, domain expertise |
| Turnaround | ✕Depends on team availability | !SLA exists, enforcement varies | ✓Free sample in 24–48 hours; audit trail on delivery |
Competitor columns are general; actual results depend on the team and provider.
Precise BPO is an India-based BPO that has handled data cleansing and deduplication for enterprise clients since 2008. Records that need a decision are reviewed by a person, and the work is logged for audit. The Precise BPO team is made up of trained, in-house specialists who can scale with project size.
We have been cleaning high-volume customer, product and database records for enterprise clients since our founding.
Our workflows are aligned to ISO 27001, GDPR and HIPAA, and every engagement is covered by an NDA.
We add capacity as a project grows, which suits both large one-time cleanups and ongoing data quality maintenance.
We work with clients in 27+ countries across North America, Europe, the Middle East, Asia-Pacific and Latin America.
Delivering from India lets us price 40–60% Below US/UK Rates, without longer turnaround or weaker security.
Rules-based matching, specialist review and multi-level QA support our 99.8% record-level accuracy.
Pricing depends on record volume, data complexity and how much requires manual investigation. Choose the model that matches your dataset and budget — or combine them. All engagements start with a free sample or pilot.
Pay only for what you process. Suits a single database export, product catalog or ad-hoc cleansing run with no recurring commitment.
Suits records where the effort varies, such as ambiguous duplicate groups, legacy databases or inconsistently structured datasets, where record counts don't reflect the review effort.
A fixed-scope, fixed-cost engagement for clearly defined cleanup projects — a full CRM cleanse, database migration preparation or a one-time legacy data cleanup.
A dedicated team, fixed monthly capacity, and predictable cost. Suits enterprises with continuous data-quality maintenance across customer, product or master data.
Answers on scope, duplicate handling, data types and pricing.
Data cleansing (also called data scrubbing) means reviewing data you already have — customer records, product catalogs, CRM entries or a business database — and fixing what is wrong before you use it for operations, reporting, migration or analytics. That covers duplicates, missing fields, inconsistent formats, outdated entries and naming problems. Our approach is human-led and rules-based rather than a fully automated pass, so records that need judgment get a specialist's review.
We clean customer and CRM records, product and SKU catalogs, supplier and vendor data, business and master databases, address and contact databases, and structured spreadsheet or CSV/Excel datasets. Work spans industries including ecommerce, retail, financial services, healthcare, insurance, logistics and manufacturing.
Yes. We find likely duplicate customer records using matching rules agreed with you, then merge, keep separate or escalate each group. Shared details alone do not make two records the same customer: family members, shared households and multi-location businesses often overlap.
Always. Every duplicate group goes through identify, compare and verify steps before a decision is made. Clear duplicates are merged according to your business rules, records that turn out to be distinct are kept separate, and anything ambiguous is escalated for client sign-off rather than removed automatically.
Yes. CRM and customer database cleansing covers deduplicating contact and account records, standardizing addresses and contact fields, filling or flagging missing fields and resolving inconsistent customer records, so your sales, support and marketing teams work from one clean source.
Yes. Product and ecommerce data cleansing covers SKU cleanup, duplicate product identification, attribute and naming standardization, pricing data review, and catalog categorization consistency.
Yes. Data standardization and normalization covers names, addresses, phone numbers, email formats, dates, product attributes, categories, units and reference values, so records follow one consistent format across your database.
Yes. Precise BPO has processed 250M+ data cleansing records to date as part of 990M+ total records processed across all services. Our 540+ In-House Team supports both ongoing programs and large one-time record cleanup projects such as CRM cleanup, database migration preparation or legacy data cleanup.
Every project runs on client-defined cleansing rules, applies human verification to records requiring judgment, and passes through multi-level QA with exception handling and escalation before final validation. The goal is to improve data quality without removing legitimate information.
Yes. We offer a free data cleansing sample or pilot so you can provide a representative slice of your dataset and cleansing rules and see the workflow, quality and expected output before committing to a larger engagement.
Data entry captures new information into a system. Data cleansing works on data you already have — reviewing existing records to correct, deduplicate, standardize and validate them. Many clients use both services together, entering new records through our data entry team while an existing database is cleaned up in parallel.
Yes. Legacy data cleansing is one of our most common engagements — profiling older databases, resolving duplicate and incomplete records built up over years, and standardizing fields that were entered under different rules at different times. This is frequently the first step before an archive, consolidation or migration project.
Yes. Pre-migration data cleansing profiles the source dataset, identifies duplicates, standardizes and validates fields, and prepares a mapped, exception-reviewed dataset ready for import. The full 7-step migration process is set out above.
Data cleansing is priced per record, per hour, per project, or as a monthly retainer, depending on record volume, data complexity and how much of the dataset requires manual investigation rather than rules-based matching. See the pricing section above, and every engagement can start with a free sample or pilot.
Data deduplication — identifying and resolving duplicate records — is one part of data cleansing, which is the broader service and also covers incomplete fields, inconsistent formatting, outdated values and standardization of names, addresses and other reference data.
Practical guides to help operations and data teams choose and evaluate a data entry outsourcing partner.
Send a representative slice of your dataset and your cleansing rules. We will return a cleaned sample within 24–48 hours, free of charge, so you can judge the quality before committing to a larger project.
Reach out to discuss your dataset and cleansing rules. Our team responds within 8 hours.
Your inquiry has been received. A member of our data cleansing team will contact you within 8 hours to discuss your project requirements.
Call us at +91 7972620994 or email info@precisebposolution.com