AI & Machine Learning Training Data · Text Annotation Experts

Text Annotation & NLP Data Labeling

Precise BPO Solution provides outsourced text annotation services, including high-volume labeling for NLP, LLM fine-tuning, sentiment analysis, chatbot training and document AI. Our 540+ in-house team in Pune, India has labeled 45M+ text records since 2017, in workflows aligned with ISO 27001, HIPAA and GDPR.
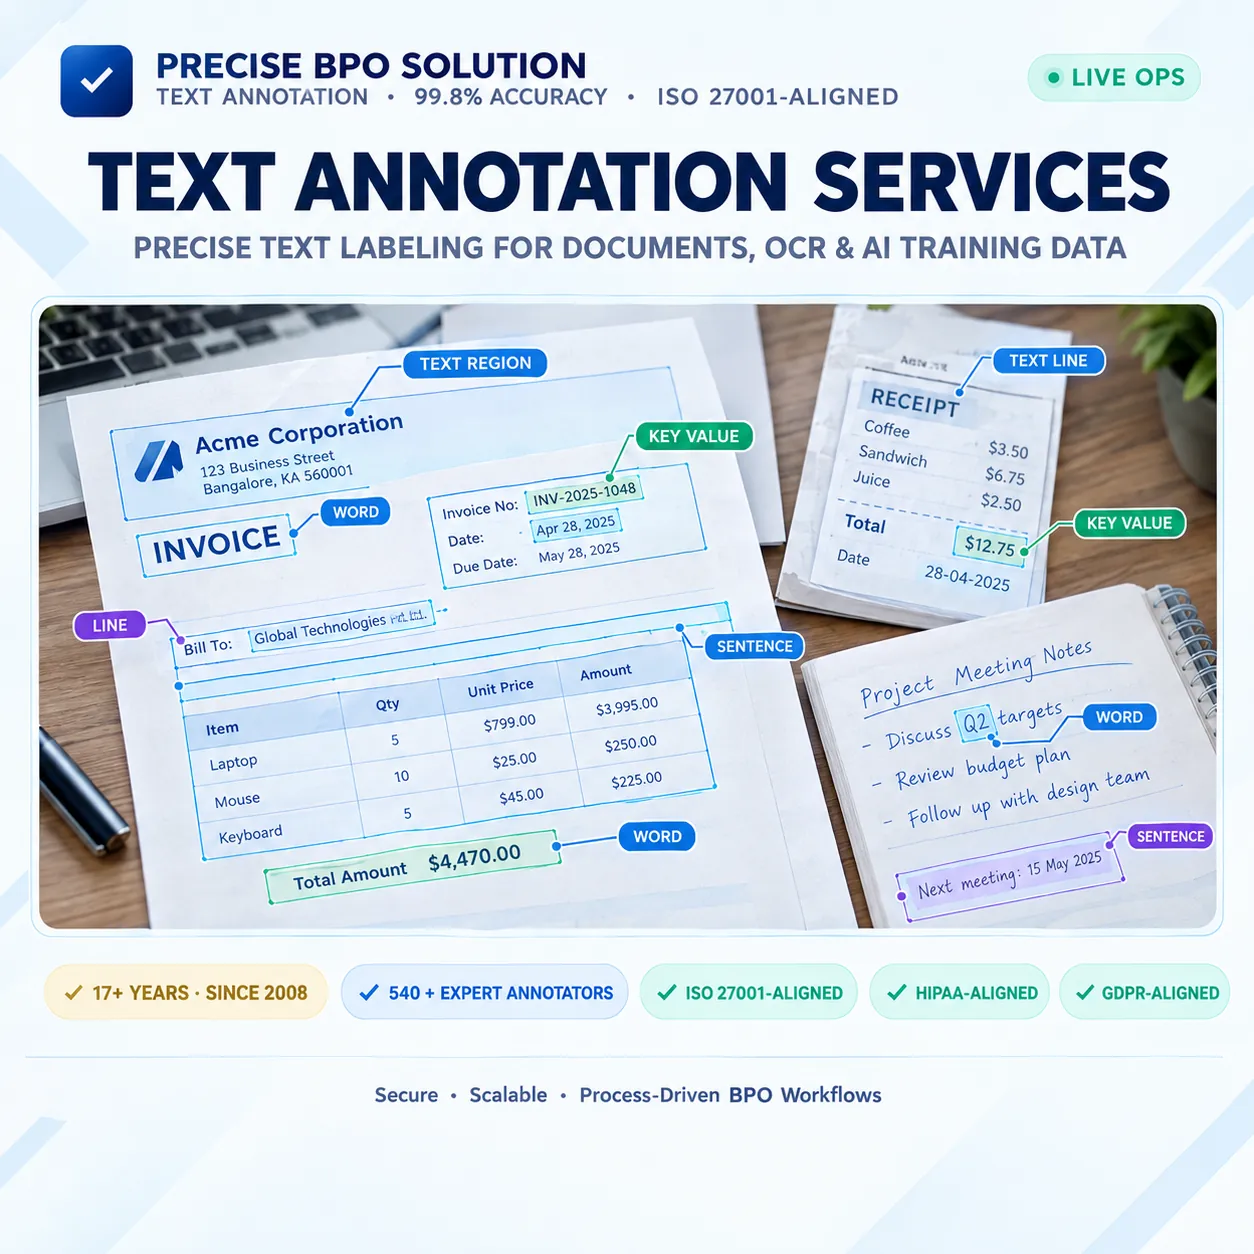
Precise BPO text annotation service — sentiment, NER, and chat data labeled for NLP models

Text Annotation at a Glance

99.8% Accuracy Target (Up To) QC-validated
45M+ Text Records Labeled Since 2017
500K+ Records/Day All NLP types
540+ Team Members In-house & NDA-bound
24–48h Turnaround Standard batch
18+ Years in Business Labeling since 2017
ISO 27001-aligned Security Standard HIPAA-aligned · GDPR-aligned

🌍 Serving enterprises across US · UK · Canada · Australia · Europe · Middle East · APAC · LATAM

📋 Quick Navigation
TXT

What is Text Annotation?

Text annotation is the process of labeling raw text (sentences, documents, chat logs, reviews, transcripts) with structured metadata such as entities, sentiment, intent, topics, or relationships, so Natural Language Processing (NLP) models and LLMs can learn to interpret language reliably. Without high-quality annotated text, even the largest language models struggle to generalize on domain-specific tasks.

It is a core part of enterprise data labeling for chatbots, search relevance, content moderation, and clinical NLP. Unlike image annotation, which labels regions of a picture (bounding box annotation for object detection, for example), text annotation captures linguistic structure: token boundaries, semantic categories, and contextual relationships within unstructured language.

Delivery is in whatever your pipeline expects: CoNLL tags, JSON/JSONL label sets, spaCy binary or BRAT standoff files, ready for spaCy, Hugging Face Transformers or your own LLM fine-tuning workflow. If your source material is on paper or in scanned PDFs, we can digitize it first through our online data entry service.

Named Entity Recognition
Tags people, organizations, locations, products, and custom domain entities within text to train extraction and search-relevance models.
Sentiment & Emotion
Reviews, support tickets, and social posts labeled with polarity and fine-grained emotion to train brand and customer-experience models.
Intent Classification
Chatbot and voice-assistant utterances tagged with underlying user intent to power conversational AI and routing systems.
Output Formats
Delivered as CoNLL, JSON/JSONL, spaCy binary, BRAT standoff or custom schemas, ready to plug into NLP training pipelines.
02

Text Annotation for NLP and AI Teams

45M+ Text Records Labeled by One In-House Team
18+
Years in business · data labeling since 2017
▲ Since 2008
45M+
Text records annotated across all projects
▲ Sentiment, NER, intent & more
540+
In-house team, NDA-bound
▲ Dedicated language & domain teams
99.8%
Accuracy target (up to), multi-stage QC validated
▲ Guideline & agreement checks
24–48h
Standard turnaround for most batches
▲ Enterprise SLA
ISO 27001-aligned HIPAA-aligned GDPR-aligned NDA

Text annotation gives NLP models the labeled examples they need to learn sentiment, entities, intent and context. Since 2017, Precise BPO has delivered datasets for sentiment analysis, named entity recognition, intent classification and document AI from our Pune delivery center, which runs 24/7 across time zones.

At Precise BPO Solution, our 540+ in-house team has delivered NLP datasets for finance, healthcare, retail, legal and customer-support teams, and has labeled 45M+ text records in total. We work in your annotation platform and with your taxonomy, so there is nothing to migrate.

For LLM fine-tuning and RLHF programs, we produce instruction and preference data to your guidelines, including response ranking and summarization quality review. We also label chatbot transcripts, intents and multilingual sentiment data. We work as an outsourced text annotation partner, so AI teams can move from pilot to production without building their own labeling team.

Every workflow follows practices aligned with ISO 27001, HIPAA and GDPR, so sensitive content is handled under controlled access. Multi-stage QA, annotation audits and feedback loops keep labels consistent from batch to batch. If your documents need de-identification, data entry or format conversion before or after labeling, we can handle that under the same NDA.

🚀
Dedicated Domain Teams for NLP & LLM Training
Our 540+ in-house team includes dedicated language and domain annotators, labeling millions of text records every month.
📐
Guidelines & Agreement Checks
Every label follows written guidelines and consistency checks, and multi-stage QC supports a target of up to 99.8% accuracy.
🔐
Aligned with ISO 27001, HIPAA & GDPR
Access controls, NDA-bound workflows and audit trails on every project.
IND

Industries We Serve

We work with healthcare, BFSI, eCommerce, technology, government, EdTech and research teams building AI and machine learning systems.

🏥
Healthcare & Medical NLP
Labeled data for clinical document classification, diagnosis-support models, medical coding, ICD tagging and patient record analysis, handled in HIPAA-aligned workflows. We also do medical image annotation for multimodal clinical AI teams.
🏦
Banking, Finance & Insurance (BFSI)
Training data for fraud detection, compliance automation, customer-intent analysis, risk scoring and financial document classification. We also offer financial data entry services for statements, forms and onboarding documents.
🛒
eCommerce & Online Marketplaces
Labels for search relevance, product attribute tagging, review sentiment and recommendation-engine classification. Our retail image annotation work covers the visual side.
💻
IT, SaaS & Technology Providers
Training data for chatbots, ticket routing, sentiment engines, workflow automation and enterprise knowledge-management tools.
⚖️
Legal & Compliance Firms
Entity and clause tagging for contract analysis, legal document summarization and regulatory review. Scanned contracts can be digitized through our legal document data entry service.
📞
Telecom & Customer Support
Annotated conversation datasets for ticket routing, intent detection, agent-assist NLP and contact-center AI.
🏛️
Government & Public Sector
Labeled data for document digitization, policy classification, large-scale text mining and multilingual government forms. Paper registration records can be digitized first through our civil registration and birth form processing service.
🎓
Education & EdTech Platforms
Labels for essay scoring, content recommendation, adaptive learning and student feedback classification. Learner surveys and feedback forms can be keyed in through our survey data entry service.

NER vs Sentiment Analysis vs Intent Classification — When to Use Which

The annotation type you pick affects both model performance and labeling cost. This comparison is meant to help NLP and ML teams choose based on the task, model architecture and dataset goals. For more detail, see our data labeling fundamentals guide.

Criteria Named Entity Recognition Sentiment Analysis Intent Classification
Task Definition Tag spans of text as entity types (person, org, location, custom) Label polarity / emotion of a sentence, review, or document Classify the underlying purpose of an utterance or query
Best for Extraction, search relevance, knowledge graphs, document tagging Brand monitoring, customer feedback, review analysis Chatbots, voice assistants, support ticket routing
Annotation Speed Moderate: span-by-span tagging Fastest: single label per text Fast: single label per utterance
Cost Efficiency Moderate: scales with entity density Highest: minimal effort per record High: efficient at volume
Output Granularity Token / span-level Document / sentence-level Utterance-level
Common Use Cases Legal, healthcare records, resume parsing, search Retail, social listening, app store reviews Conversational AI, IVR systems, customer support

Not sure which annotation type fits your project? Talk to our team and we'll recommend an approach based on your model, languages and dataset.

NLP

Text Annotation & Labeling Capabilities

We label text for NER, sentiment, intent, classification, semantic tagging, topics, toxicity, multilingual datasets and LLM fine-tuning, at the volumes large training pipelines need. You work with one team, one QA standard and one contract, including on multilingual projects.

✓
Named Entity Recognition (NER)Entity tagging for people, organizations, locations, dates, products and custom domain entities, aligned to your ontology and schema.
✓
Sentiment & Emotion AnalysisSentiment labeling at document, sentence and aspect level, covering polarity, emotion categories and mixed or subtle sentiment, for analytics and recommendation models.
✓
Intent Detection & ClassificationMulti-class intent labeling for chatbot and virtual assistant training, with support for hierarchical taxonomies, ambiguous utterances and client-defined intent schemas.
✓
Semantic & Relation AnnotationSemantic role labeling, coreference resolution and relation extraction linking entities across sentences, for knowledge graph and semantic search models.
✓
Toxicity & Safety AnnotationContent moderation labeling for hate speech, offensive language, spam, misinformation and harmful content, with context-aware labels for trust & safety models.
✓
LLM Fine-Tuning & RLHF DataHuman feedback, preference ranking, instruction-response pairs and supervised fine-tuning datasets, built to your rubric for LLM alignment.
✓
Multilingual Text DatasetsText annotation in English (US, UK, Australian and Canadian), Hindi and Marathi, by native-speaker annotators, for multilingual NLP models and international AI products.
✓
Custom Taxonomies & Export FormatsCustom annotation guidelines, domain ontologies and class hierarchies, delivered in JSON, CSV, XML, CoNLL or client-specific formats ready for direct model ingestion.
✓
Text Summarization & Entity LinkingAbstractive and extractive summarization labeling for long-document AI, plus entity linking that resolves mentions to a knowledge base — supporting search, retrieval and knowledge graph applications.
Send Us Your Dataset Brief →
Illustration showing NLP text annotation and labeling capabilities including NER, sentiment, intent, semantic tagging, and multilingual datasets.
"Apple Inc. reported strong Q3 earnings in Cupertino yesterday." ORG LOC DATE SENTIMENT: POSITIVE TOPIC: FINANCE entity_conf: 0.98 sentiment_conf: 0.96 QC ✓ · accuracy target: up to 99.8% schema: NER_v3 "Users loved the new interface — support tickets dropped 40%." SAMPLE ANNOTATION Up to 99.8% accuracy · ISO 27001-aligned · HIPAA-aligned SAMPLE

Our Text Annotation Workflow

Six steps take a project from scoping to delivery, with QC built into every batch.

1

Scoping & Requirements

Define annotation goals, NLP taxonomy, label schema, edge-case rules, and domain-specific guidelines with your AI or product team before any labeling begins. Annotator briefing and pilot batch scoping included.

Label taxonomy Guideline creation Edge-case mapping SLA setup
2

Data Intake & Preparation

Text corpora, documents, chats and reviews arrive by encrypted transfer and are cleaned, normalized and split into batches on secure, ISO 27001-aligned infrastructure.

Encrypted transfer NDA protection ISO 27001-aligned Data normalization
3

Annotation & Labeling

Specialized annotators label the data to your guidelines and domain rules, in your preferred tooling or ours.

NER tagging Sentiment labeling Intent classification LLM fine-tuning data
4

Multi-Stage Quality Check

Multi-stage QC covering peer review, senior annotator validation, inter-annotator agreement scoring, and automated consistency checks, aiming for a target of up to 99.8% accuracy on every delivered batch.

Peer review IAA scoring Consistency audit Reviewer sign-off
5

Client Review & Alignment

Annotated batches are submitted for client review. Feedback goes through structured revision cycles, so the taxonomy stays aligned as guidelines and model requirements change.

Batch submission Feedback loop Guideline refinement
6

Final Delivery & Scaling

AI-ready datasets delivered in JSON, CSV, XML, CoNLL, or custom formats via secure transfer. Ongoing batch processing, active learning support, and scaling as volumes grow on long-term NLP programs.

JSON / CSV / XML CoNLL / custom Secure delivery Ongoing support
Compliance & Security
🔒 ISO 27001-aligned workflows
🏥 HIPAA-aligned data handling
🇪🇺 GDPR-aligned processing
📋 NDA on every engagement
🔧 Platform-agnostic delivery
UC

Text Annotation Use Cases

Recent projects across financial services, healthcare, eCommerce, government, social media and legal, for clients in 27+ countries.

🇬🇧 Financial Services · UK

Financial Document Classification & NER

Client Need: Structure 2.5M+ financial documents — statements, forms, onboarding packets — for a UK fintech platform's automated compliance engine.
Solution: NER and compliance tagging on standardized datasets, in ISO 27001- and GDPR-aligned workflows. We also run financial document data entry work for banks and fintechs.
  • 60% reduction in manual review load
  • Volume: 2.5M+ documents
🇨🇦 Healthcare · Canada

Clinical Text Annotation for Diagnostic NLP

Client Need: Annotate 800K+ clinical notes for a diagnostic NLP model, with strict handling of sensitive patient records across multiple hospital networks.
Solution: Symptoms, medications, ICD codes and clinical observations tagged by domain-expert annotators, with multi-stage QA in HIPAA-aligned workflows. Hospital networks often pair this with our medical claims data entry service for end-to-end record digitization.
  • 28% improvement in diagnostic model accuracy
  • Volume: 800K+ clinical notes
🇪🇺 eCommerce · EU

Customer Review Sentiment & Attribute Tagging

Client Need: Process 4M+ customer reviews across 14 product categories for sentiment and attribute labeling to power a search and recommendation engine.
Solution: Sentiment polarity, aspect-level tagging, product-issue signals and feature extraction, structured for direct use in analytics and ranking models. We also handle market research data entry for teams running customer research.
  • 25% improvement in search relevance scores
  • Volume: 4M+ reviews across 14 categories
🌍 Government · Middle East

Government Document Entity Extraction

Client Need: Annotate 3M+ government documents — national IDs, legal forms, and approval workflows — to automate a public-sector processing platform.
Solution: Field classification, multi-entity extraction and multi-category document tagging on a custom taxonomy, in secure NDA-bound workflows. We run similar work in our government registration form processing service for public-sector clients.
  • 70% of document workflows automated
  • Volume: 3M+ documents
🌏 Social Media · APAC

Social Media Toxicity & Content Moderation

Client Need: Detect toxicity, spam, hate speech, and trending sentiment across 4M+ social media posts for a regional content moderation AI platform.
Solution: Context-aware toxicity labeling, harmful-content tagging and sentiment signals, structured for training real-time moderation models. Image and video review is available through our explicit content annotation service.
  • 45% improvement in moderation accuracy
  • Volume: 4M+ social posts
🇺🇸 LegalTech · US

Legal Contract NER & Clause Classification

Client Need: A US legaltech platform required high-precision NER and clause-level classification across 800K+ contract documents for an AI-powered contract review engine.
Solution: Domain-expert legal annotators tagged parties, obligations, dates, liabilities and clause types, with multi-stage QA, a custom taxonomy and JSON/CSV output. Full-text digitization comes from our legal data entry team.
  • Contract review time reduced by 55%
  • Clause extraction precision improved by 31%
  • Volume: 800K+ contracts
LLM

LLM & Generative AI Annotation

Large language models need precisely structured human feedback data to align, generalize, and perform safely at scale. Precise BPO provides RLHF preference datasets, supervised fine-tuning corpora and safety data.

🧠

RLHF & Preference Ranking

Human preference ranking across model response pairs, critique feedback and reward model training data, annotated by domain-trained evaluators following your scoring rubrics.

Pairwise Ranking Likert Scoring Critique Feedback
📝

Supervised Fine-Tuning (SFT) Datasets

Instruction-response pairs, prompt-completion datasets and domain-specific conversation corpora, structured to spec and ready to load into your fine-tuning pipeline.

Instruction Tuning Prompt–Completion Pairs Domain Adaptation
🛡️

Safety, Alignment & Red-Teaming Data

Harmful output identification, refusal annotation, bias detection labeling and adversarial prompt classification.

Harm Detection Bias Labeling Red-Teaming

How LLM annotation differs from standard NLP labeling

Unlike standard NLP labeling where annotators apply fixed categories to text, LLM training data requires evaluators to make nuanced judgments about helpfulness, truthfulness, harmlessness, and instruction-following quality — often across long multi-turn conversations with no single "correct" answer.

Precise BPO's LLM annotation teams are briefed on your model's intended behavior, persona, and output standards before labeling begins. Every annotator signs an NDA and works under multi-stage QA review. For ground-truth and classification work alongside generative AI, see our full data labeling services.

Send Us Your LLM Data Brief →
RLHF
Preference data · Reward modeling · Human feedback loops
SFT
Supervised fine-tuning · Instruction datasets · Domain corpora
DPO
Direct preference optimization datasets · Contrastive pairs
RAG
Retrieval relevance labeling · Chunk quality scoring

Tools, Formats & Secure Transfer

We work in your existing annotation tools or recommend a stack that suits the project. Our annotators use Prodigy, Doccano, Label Studio and several other platforms. Need source files reformatted before labeling begins? Our document and data conversion team handles that as part of the same engagement. No lock-in.

🖥️Annotation Platforms
Prodigy Doccano Label Studio Labelbox INCEpTION brat (BRAT Rapid Annotation Tool) Scale AI Platform Custom / In-house Tools
📁Export Formats
CoNLL-2003 / IOB-BIO tagging JSON / JSONL spaCy binary (.spacy) BRAT standoff format CSV tabular export XML Custom schema on request
🤖Pipelines We Deliver Into
spaCy Hugging Face Transformers NLTK Stanford CoreNLP / Stanza Rasa NLU PyTorch / TensorFlow LLM fine-tuning formats (OpenAI, Anthropic) Custom pipeline formats
🔒Secure Transfer
Encrypted SFTP AWS S3 (private bucket) Google Cloud Storage Azure Blob Storage Secure client portals Encrypted email delivery
10

Why Choose Precise BPO for Text Annotation?

Precise BPO is an India-based annotation company, in business since 2008. We deliver text and NLP annotation to AI teams worldwide, with an in-house team and a QA process built around your guidelines.

Start a Free Pilot →
⚡
Founded in 2008

Text and NLP annotation since 2017.

👥
540+ In-House Team

Specialists in healthcare, legal, BFSI, retail and tech. No crowdsourcing: every annotator is in-house and under NDA.

🔒
Security & Compliance

NDA-bound workflows and automated security audits protect sensitive clinical, legal and financial text from intake to delivery.

🎯
Target of Up to 99.8% Accuracy

Multi-stage QC combining inter-annotator agreement, senior review, and automated consistency checks so labels stay precise from batch to batch.

💰
40–60% Below US/UK Rates

Delivery from India with flexible per-record, per-hour and retainer pricing, and a free pilot before you commit.

🔧
Works in Your Tools and Formats

We annotate in your preferred tool (Label Studio, Prodigy, Doccano or a custom pipeline) and deliver in JSON, CoNLL, CSV, JSONL or any client schema.

Precise BPO text annotation team at work

3-Tier QA Pipeline — How We Target Up to 99.8%

Every batch passes three quality-control gates before it goes to the client. The tiers are designed to catch entity-boundary errors, label inconsistencies and schema drift early, before they carry through a batch.

Tier 1 Annotator + Peer
→
Tier 2 Automated Validation
→
Tier 3 Expert Audit + Delivery
T1

Annotator Self-Check & Peer Review

The annotator does a first pass and a senior peer cross-checks it. This catches entity boundary errors, mislabeled spans, intent mismatches, and guideline deviations before any automated scoring.

Annotator reviews entity boundaries, label assignment, and tag consistency against project guidelines before submitting
Senior annotator cross-checks: schema adherence, overlapping spans, and multi-class label correctness across the batch
Batches failing T1 threshold are returned for correction before advancing to T2
T1 Exit Accuracy Target95%+
Schema Compliance97%+
T2

Automated Validation & Consistency Check

An automated layer that validates tag structure, checks inter-annotator agreement, detects label drift and flags statistical outliers for human re-review.

Inter-annotator agreement (IAA) scoring run against reference annotations — entity and label precision evaluated against project-specific thresholds
Schema validation: malformed tags, overlapping entities, and inconsistent label sets flagged and returned for correction
Statistical outlier scan: anomalous entity density, class distribution, or sentiment skew flagged for human review
T2 Exit Accuracy Target98%+
Average IAA Score0.97
T3

Expert QA Audit, Client Loop & Final Delivery

QA Lead conducts random sampling plus full-batch review on high-stakes NLP datasets — re-checking entity tags, sentiment labels, and intent classes against the guideline. Client feedback loops are built in — corrections applied and re-verified before final sign-off and delivery.

Random sampling audit: QA Lead reviews 10–20% of records per batch (100% on clinical / legal text annotation projects)
Client sample review: 50–100 annotated records delivered for client acceptance before full batch proceeds
Iterative feedback: corrections applied, re-scored through T2 pipeline, and re-delivered with full audit trail
Final Delivery Accuracy Target (Up To)99.8%

Throughput Capacity

Records / Day (Peak)500K+
Records / Month (Capacity)10M+

In-House Team vs. Generic BPO vs. Precise BPO

A side-by-side look at in-house teams, generic BPOs and Precise BPO, for AI leads, NLP engineers and procurement teams who need to justify outsourcing.

Criteria In-House Team Generic BPO Precise BPO
Labeling Accuracy Depends on reviewer fatigue; rarely any linguistic QC Label checks are often inconsistent ✔ Target of up to 99.8% accuracy, 3-tier QA pipeline
Setup Time Typically 6–10 weeks (hire, train, tool) Typically 3–5 weeks ✔ Pilot starts within 48 hours after NDA; delivery in 24–48 hours
Scalability for Surge Volumes ❌ Fixed headcount, slow ramp ⚠ Limited, delays common ✔ 540+ team, scales within days
Cost vs US/UK Rates Baseline (salary + infra) Typically 25–35% savings ✔ 40–60% Below US/UK Rates
Security Standard ❌ Often informal ⚠ Varies by provider ✔ Aligned with ISO 27001, HIPAA & GDPR
Multilingual & Domain Coverage ⚠ Limited language depth ⚠ Not domain-specialized ✔ English, Hindi, Marathi; legal & medical teams
Inter-Annotator Agreement Tracking ⚠ Rarely measured ⚠ Often not reported ✔ IAA scored on every batch
Free Trial / Pilot — Internal ramp-up instead ❌ Rarely offered ✔ Free pilot batch, no commitment
13

Text Annotation Pricing & Engagement Models

No platform fees and no lock-in. Pricing is structured around your volume and timeline, and every engagement starts with a free pilot batch. See our pricing guide for a detailed look at US vs India benchmarks.

📝
Best for: Standard text batches
Per Record

Pay per annotated sentence, review, or short text snippet. Ideal for sentiment datasets, NER tagging, or one-off intent classification projects at a predictable per-unit cost.

📄
Best for: Long-form documents
Per Document

Priced per document or transcript. Purpose-built for contract review, medical records, and call transcript annotation where document count is the natural unit of work.

⏱
Best for: Complex / dense data
Per Hour

Hourly model for high-complexity annotation (nested entity tagging, multi-label classification, dense relation extraction) where per-record pricing doesn't reflect actual annotation effort.

🔄
Best for: Ongoing pipelines
Monthly Retainer

A dedicated text annotation team at fixed monthly capacity. Suited to enterprises and AI labs with continuous labeling needs, active learning pipelines, or LLM fine-tuning workflows.

Volume discounts available from 1M+ records/month. White-label pricing for BPO partners.
All models include an NDA, ISO 27001-aligned security controls and a free pilot batch.
Get a Text Annotation Quote →

24/7 Text Annotation Across Time Zones

Our Pune delivery center runs 24/7, with shifts timed to cover the US, UK, EU, APAC, Middle East, Australia, Canada and LATAM.

Annotation floor live now · --:-- UTC
North America
USA · Canada
--:--EST/PST
United Kingdom
England · Scotland · Wales
--:--GMT/BST
Australia & NZ
Australia · New Zealand
--:--AEST
Europe
Germany · France · Netherlands · Nordics
--:--CET/CEST
Asia-Pacific
Singapore · Japan · India · SEA
--:--IST/SGT
Middle East & Africa
UAE · Saudi Arabia · South Africa
--:--GST
Latin America
Brazil · Mexico · Argentina · Colombia
--:--BRT/CST
Remote & Custom
Other regions on request
--:--24/7
Three overlapping shifts, so work hands over without a gap Red marker = current time (UTC)
APAC shift
EMEA shift
Americas shift
00:0004:0008:0012:0016:0020:0024:00
%

Annotation Performance by Task Type

Typical accuracy, throughput and turnaround by task type.

Annotation Type Accuracy Avg. Throughput / Day Typical Turnaround Consistency Performance
Named Entity Recognition (NER) Up to 99.8% 80,000+ records 24–48 hours Inter-annotator 97%+
Sentiment & Emotion Tagging 99.5% 100,000+ records 24 hours Inter-annotator 96%+
Intent & Utterance Classification 99.7% 120,000+ records 12–24 hours Inter-annotator 98%+
Document Tagging & Classification 99.6% 50,000+ pages 48–72 hours Inter-annotator 96%+
Toxicity & Content Moderation Labeling 99.2% 150,000+ posts 24 hours Inter-annotator 95%+
Semantic Role & Relation Tagging 99.3% 40,000+ records 48 hours Inter-annotator 95%+
Search Relevance & Query Labeling 99.6% 90,000+ queries 24–36 hours Inter-annotator 97%+
★

What Our Clients Say

Feedback from clients in the US, Canada and Germany.

"
We needed 1.5 million records labeled for NER across three different ontologies. Precise BPO finished in under three weeks, and accuracy stayed above 99.7% the whole way through.
JM
James M.
Head of AI Engineering
FinTech Company, USA
"
Our clinical NLP pipeline came with strict HIPAA requirements, and Precise BPO worked within them. They labeled more than 800,000 clinical notes for us and the quality was good. Their process documentation and audit trails gave our compliance team what it needed.
SP
Sarah P.
VP Data Science
Healthcare SaaS, Canada
"
We sent them more than four million product reviews for sentiment and intent tagging. Turnaround was quick, accuracy stayed above 99.5%, and they kept us updated throughout. It also cost us over 60% less than doing the work in-house.
LK
Lars K.
Product Analytics Lead
eCommerce Platform, Germany
?

Text Annotation — FAQs

Answers on scope, accuracy, output formats, languages, large projects, security and pricing.

Text annotation is the labeling of text with entities, sentiment, intent, topics or relationships so machine learning models can learn from it. Chatbots, search engines and clinical NLP systems all depend on large volumes of accurately labeled text. See our guide to data labeling for broader context.

Text annotation can be applied to documents, customer messages, product reviews, emails, chat logs, social media posts, clinical notes, legal contracts, financial reports, and any other unstructured text source.

Common techniques include Named Entity Recognition (NER), sentiment tagging, intent classification, text classification, topic labeling, part-of-speech tagging, coreference resolution, relation extraction, and semantic annotation. They are used to build search systems, conversational AI and analytics pipelines.

NLP models and LLMs learn patterns, intent and context from labeled examples, so better labels mean better accuracy on classification and entity extraction. For LLMs, human feedback data (such as RLHF preference rankings) and supervised fine-tuning datasets are what align the model to your use case.

Yes. We annotate text in English (US, UK, Australian and Canadian variants), Hindi and Marathi, using native-speaker annotators and language-specific guidelines. If your project needs another language, ask us and we will tell you whether we can cover it.

We keep labels consistent with written guidelines, shared label definitions, inter-annotator agreement tracking, multi-stage human review and automated consistency checks. The same rules apply to similar text across batches, so the model does not learn conflicting patterns. See our annotation governance framework for how we enforce these standards.

Annotated text is delivered in JSON, CSV, XML, CoNLL, JSONL, or custom schemas matched to your pipeline. These load directly into spaCy, Hugging Face, NLTK and most ML platforms.

Pricing depends on data volume, annotation complexity, language coverage, and turnaround requirements. We price per record, per document, per hour or as a monthly retainer. Our pricing typically runs 40–60% below US/UK rates. See our data labeling pricing guide or request a tailored quote.

Our workflows are aligned with ISO 27001, HIPAA and GDPR. For every NLP dataset we apply access controls, secure data transfer, NDA-bound annotators, audit trails, and data minimization practices. This matters most for healthcare NLP, legal AI and any project with personally identifiable information (PII).

Guides & Resources

Practical guides on data labeling, annotation pricing, governance and vendor selection, for ML engineers and AI data leads.

Start Today

Turn Raw Text into AI-Ready Datasets

Send us a sample and we'll label a free pilot batch, so you can judge the quality before committing.

20

Start Your Text Annotation Project

Our 540+ in-house team handles NER, sentiment analysis, intent classification, LLM fine-tuning and multilingual datasets from our Pune office. If you also need image or video annotation, we can run it in the same engagement through our data labeling services. Meet the team or request a free pilot below.

📞
Phone & WhatsApp
📍
Office
B3, Sant Namdev Marg, Varundavan Colony, Walhekarwadi, Gurudwara Colony, Nigdi, Pimpri-Chinchwad, Maharashtra 411033
Compliance Aligned
🔒 ISO 27001-aligned 🏥 HIPAA-aligned 🇪🇺 GDPR-aligned

Request a Free Pilot

Get a response within one business day — no commitment required.

Aligned with ISO 27001, HIPAA & GDPR · NDA on every engagement

📝

Thank you. We've received your request.

Our NLP annotation specialists will review your requirements and respond within one business day with a tailored proposal and pricing estimate.